Evaluation ReportActive
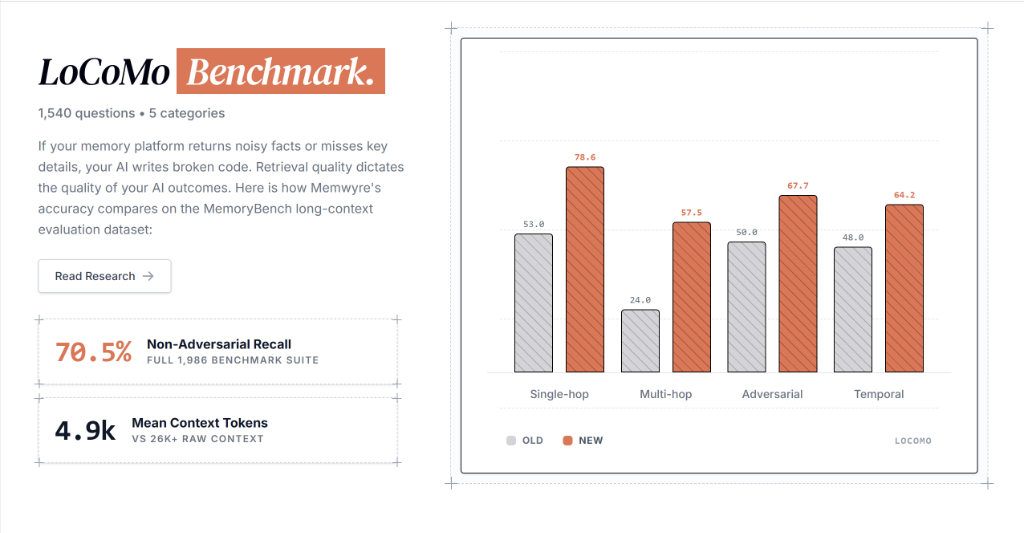
The LoCoMo Benchmark Report
Our core evaluation matrix checking long-context recall, entity traversal, and temporal consistency across 1,540 simulated developer query runs.
ACCURACY: 70.5% | HIT@10: 79.9%Read Study
Peer-reviewed benchmark datasets, architecture studies, and evaluations exploring hierarchical entity graphs, context compression, and stateful agent systems.
Our core evaluation matrix checking long-context recall, entity traversal, and temporal consistency across 1,540 simulated developer query runs.
Explore the technical architecture of AI memory, from flat vector embeddings to hierarchical entity graphs, and how it solves LLM amnesia.
The fundamental engineering differences between passive semantic vector tables and active cognitive agent memory layers with Ebbinghaus decay.
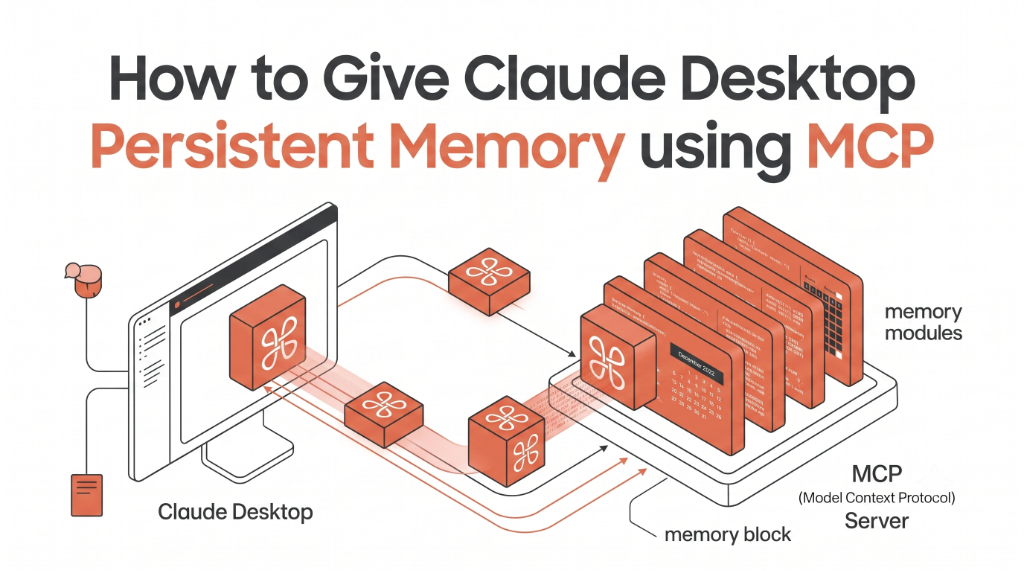
Prompt engineering is dead. Learn how Context Engineering and hierarchical entity graphs replace standard RAG for production AI agents.
Access open benchmarks, stateful context graphs, and research datasets. Set up in under 2 minutes.